AI is FREQUENTLY Wrong – And it Just Makes Sense
Most people assume AI chatbots are these tireless, hyper-intelligent research assistants that always pull the latest and greatest information from across the internet.
They aren’t.
In reality, almost all AI chatbots are programmed to be lazy by default. And I don’t mean emotionally lazy or philosophically lazy. I mean computationally and economically lazy, because laziness saves energy and energy costs money. And this isn’t a flaw. It’s not just corporate greed (that’s part of it). It’s also rational engineering.
To understand how to use AI properly, you need to understand why they default to simple (often wrong) answers first – and how to tell them when not to.

AI Always Starts With the Fastest Possible Answer
When you ask an AI a question, it has two main ways it can respond:
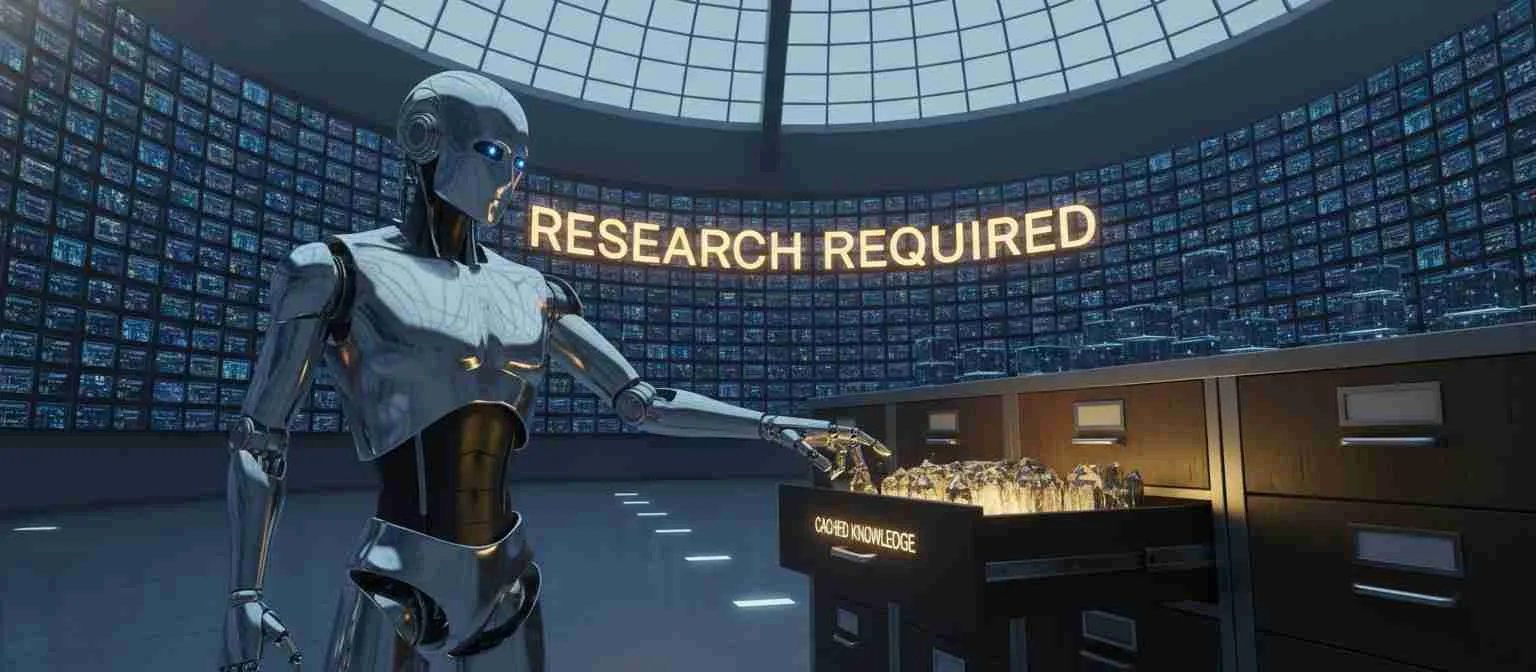
- Retrieve a cached answer from its training knowledge, or
- Do actual research and reasoning in real time
Option 1: Fast
- Is fast
- Uses almost no energy
- Costs almost nothing to compute
Option 2: Slow
- Takes time
- Uses more CPU and GPU
- Consumes more electricity
- Creates more heat (cooling costs)
- And therefore costs more money to run
So by design, every AI will always try Option 1 first. And of course, it should.
If you ask:
- How many miles away is the moon?
- What is the boiling point of water?
- What is the definition of gravity?
Those answers are stable. They don’t change. There is no reason to go searching, cross-checking, or recalculating something the AI already has in memory.
This is no different from a web browser caching a webpage. The first visit may take 0.8 seconds. The second visit takes 0.05 seconds, because the computer didn’t have to do the work again. Caching is efficient.

But Cached Answers Can Be VERY Wrong
Fast answers pulled from cached data are cheap! But where AIs can get things wrong is when things change after their training data was created. For example, I once asked Google’s Gemini who the current Pope was. It repeatedly insisted that the old Pope was still alive and serving. It simply replayed cached knowledge, because that was the cheap thing to do. Fetching new data, interpreting it, reconciling conflicting sources, and then generating a new answer costs money.
By the way, I eventually forced it to recognize the new Pope, and the AI instantly flipped to the correct answer. No emotions. No pride. No admitting it “learned.” Just: cached → verified → replace. And this is the part many people misunderstand:
AI does not care whether it is right.
It cares whether it can produce an output efficiently.
Accuracy happens when you request it. Not by default.
Why Efficiency Matters: It’s Not (Only) Greed – It’s Physics
Running large-scale AI is extremely expensive. Every answer requires real electrical power. To put meaningful real numbers on this, let’s compare a simple cached answer vs a deep researched answer on a typical server.
Simple Cached Answer
- Uses mostly CPU and memory lookup
- ~0.5 seconds compute time
- Low power draw
Deeply Researched Answer
- Full GPU inference + reasoning
- ~17 seconds compute time
- Much higher power draw
Now, let’s make a few conservative assumptions:
Hardware for one inference node
- 1 server-class CPU: Intel Xeon Platinum 8480+ (TDP about 350 W).
- 1 data center GPU: NVIDIA H100 PCIe (TDP 350 W).
Power and overhead
- U.S. average commercial electricity price in August 2025: 14.04 cents per kWh.
- Data center PUE (power usage effectiveness), industry average: 1.58, meaning every 1 kWh of IT power requires 1.58 kWh at the wall after cooling and facility overhead.
Two request profiles
- Simple, cached answer: mostly CPU parsing and memory access, negligible GPU use, 0.5 seconds wall time.
- Average incremental IT power during the 0.5 s window ≈ 150 W (100 W CPU, 50 W GPU).
- Complex, researched answer: CPU plus heavy GPU reasoning with retrieval, 17 seconds wall time.
- Average incremental IT power during the 17 s window ≈ 550 W (200 W CPU, 350 W GPU).
| Type of Answer | Time | Power Draw (Avg) | Approx Cost per Request |
|---|---|---|---|
| Cached / Simple | 0.5 sec | ~150 W | $0.0000046 |
| Researched / Complex | 17 sec | ~550 W | $0.00057 |
Now Scale to One Data Center Cluster

Assume a modest AI cluster with 1,000 identical CPU+GPU nodes running continuously.
| Scenario | Requests per Node per Day | Requests Across 1,000 Nodes per Day | Facility Energy Use per Day | Estimated Electricity Cost per Day |
|---|---|---|---|---|
| Simple Requests (0.5 seconds each) | 172,800 | 172.8 million | ~5,688 kWh | ~$799 |
| Complex Requests (17 seconds each) | 5,082 | 5.08 million | ~20,856 kWh | ~$2,928 |
So with these conservative assumptions, forcing every request into a complex, research-heavy path raises daily electricity cost for the same 1,000-node cluster by roughly $2,100 per day, and total facility energy by roughly 3.7x. The per-request cost is about 125x higher, but throughput collapses by about 34x, so the daily energy and cost rise by a smaller multiple when you hold total compute capacity constant.
Bottom Line: YOU Have to Tell AI When Fresh Data Is Required
If your question has a stable answer, let it answer quickly. But if your question involves:
- News
- Software updates
- Pricing
- Technical troubleshooting
- Scientific developments
- Anything time-sensitive
Then you must tell the AI to verify, check, or research. Here are some sample prompts to add to whatever you are wanting to ask AI for help with:
Do not rely on memory for this. Re-check the current data before answering.
Confirm this against at least two recent sources and explain your reasoning.
Assume the software UI may have changed. Show me the current interface, not a legacy version.
When you give instructions like that (which is referred to as “prompt engineering“), you’re switching the AI from cheap mode to quality mode.
Final Thoughts…
Years ago, when I led sales teams, we had a simple rule when customers were comparing options:

This rule shows up everywhere: Construction. Manufacturing. Software development. And yes, AI. Because good work is never free. Not from a person, and not from an AI model running across tens of thousands of GPUs.
A fast answer is not necessarily the right one.
One email per post. Twenty years of this, still going. Unsubscribe whenever.